
A Large Language Model (LLM) like the one powering a chatbot is incredibly knowledgeable about general information from the internet. But ask it about your company's internal HR policy or the notes from your last project meeting, and it will draw a blank. Its knowledge is frozen in time and limited to public data. Retrieval-Augmented Generation (RAG) is the architectural pattern that solves this problem.
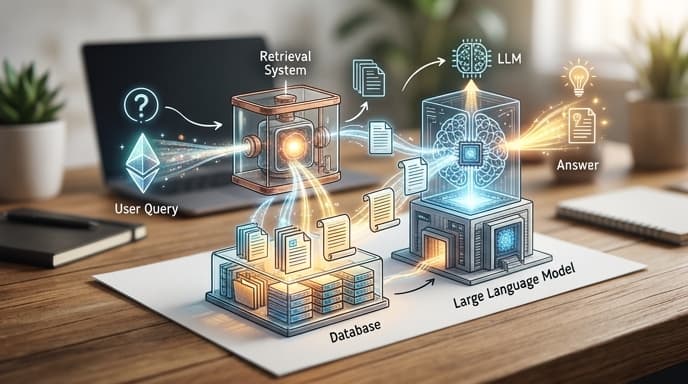
RAG gives an LLM a superpower: the ability to consult a private knowledge base before answering a question. This makes the model's responses more accurate, relevant, and trustworthy, as they can be grounded in specific, verifiable facts from your own data. It's the difference between a generalist and a subject-matter expert.
How RAG Works: The Simple Version
Imagine you have a smart assistant, but its library is empty. You want it to answer questions about a set of books (your documents). The RAG process works like this:
- You ask a question: 'What was decided about the Q4 budget?'
- The Retriever: Instead of asking the smart assistant directly, a 'librarian' (the retrieval system) first searches your books for the most relevant pages about the 'Q4 budget'.
- The Augmentation: The librarian hands the smart assistant your original question plus the relevant pages it found.
- The Generation: Now, the assistant uses its powerful language skills to read the provided pages and formulate a precise answer to your question based only on that information.
This process ensures the answer is based on your documents, not the assistant's general knowledge, which dramatically reduces the chance of the LLM 'hallucinating' or making things up.
The Developer's View: The RAG Workflow
For those building with AI, the RAG pattern involves a few key components. While the tools can vary, the workflow is generally consistent.
- 1. Indexing (The 'Library' Setup): You first need to process your documents. This involves breaking them down into smaller chunks and converting each chunk into a numerical representation called an embedding using an embedding model. These embeddings are then stored in a specialized database, often a vector database, which is optimized for finding similar chunks.
- 2. Retrieval (Finding Relevant Info): When a user asks a query, the query is also converted into an embedding. The vector database then performs a similarity search to find the document chunks whose embeddings are 'closest' to the query embedding. These are the most relevant pieces of information.
- 3. Generation (Answering the Question): The retrieved chunks of text are combined with the original user query into a detailed prompt. This augmented prompt is then sent to the LLM. The prompt essentially instructs the LLM: 'Using only the following context, answer this question.' The LLM generates a response based on this provided context.
Where RAG Falls Short
RAG is a powerful tool, but it's not a silver bullet. Its effectiveness is highly dependent on the quality of the retrieval step. If the system can't find the right information, the LLM can't answer the question correctly. This is often called the 'lost in the middle' problem, where even if the right context is retrieved, it can be buried among less relevant chunks.
Furthermore, RAG is best suited for question-answering and summarization based on existing facts. It is less effective for tasks that require a change in the model's style, tone, or underlying reasoning, which is where another technique called fine-tuning might be more appropriate.
Frequently Asked Questions
Is RAG the same as fine-tuning an LLM?
No. Fine-tuning involves retraining the LLM's internal weights on new data to change its behavior or teach it a new skill. RAG, on the other hand, provides external knowledge to a model at the time of the query without changing the model itself. RAG is generally faster, cheaper, and better for knowledge-based tasks.
Does RAG stop AI hallucinations?
It significantly reduces them by grounding the model's response in specific, provided text. However, it doesn't eliminate them entirely. The LLM could still misinterpret the provided context or generate a response that isn't fully supported by it.
What kind of data can I use with RAG?
You can use almost any kind of text-based data: PDFs, Word documents, website content, knowledge base articles, or transcripts. The key is the ability to extract clean text to be indexed.
Key Takeaways
- Retrieval-Augmented Generation (RAG) enhances LLMs by connecting them to external, private knowledge bases.
- The process involves retrieving relevant document chunks and providing them to the LLM as context along with the user's query.
- RAG makes AI responses more accurate, verifiable, and relevant to specific domains.
- The core technical workflow includes indexing data into a vector database, retrieving relevant chunks, and generating a response.
- While powerful, RAG's effectiveness depends entirely on the quality of its information retrieval step.
Related Reading
- An Introduction to Prompt Engineering Patterns
- Vector Databases: What Are They and Why Do They Matter?
- Fine-Tuning vs. RAG: Which Approach to Choose?